Most of us trust our own test suite. The tests are green, coverage is high: you release without worrying. It is an equation we take for granted (tests pass → code is healthy), and nearly always it works.
Nearly. Because “the tests pass” and “the code works” are not the same thing. And the difference gets paid for: it is exactly there that, one day, something breaks in production on code that was covered, tested, green. And no test had noticed.
It happened to me. I turned it into a talk at Working Software 2026: how I got there, how I found out, and the tools I use today to avoid going through it again. Here is the same path.
The story
A few years back I had worked on a project. No tests: “we will get to it later, there is a deadline”. The software went to production, I left the company, years passed. Then they called me: “we still use it, fancy adding something?”
I opened the repo. Thousands of lines, years of sediment, and in the tests directory essentially nothing.
I did it properly: domain specifications before a single test, the suite generated with AI agents, CI standing. At the end: 93% coverage (93% of the code executed by at least one test), all green. Satisfying.
Then a message: “hey, X broke after the last update”.
How was that possible? The tests passed, that feature was covered. And yet the suite had not made a sound.
The system under examination
To make it concrete I use the same example as the talk: a small order-management flow. An OrderService acts as the orchestrator: it receives an Order (the customer and the list of products), calculates the subtotal, then delegates the discount to a DiscountService and the shipping cost to a ShippingService, and finally assembles the result.
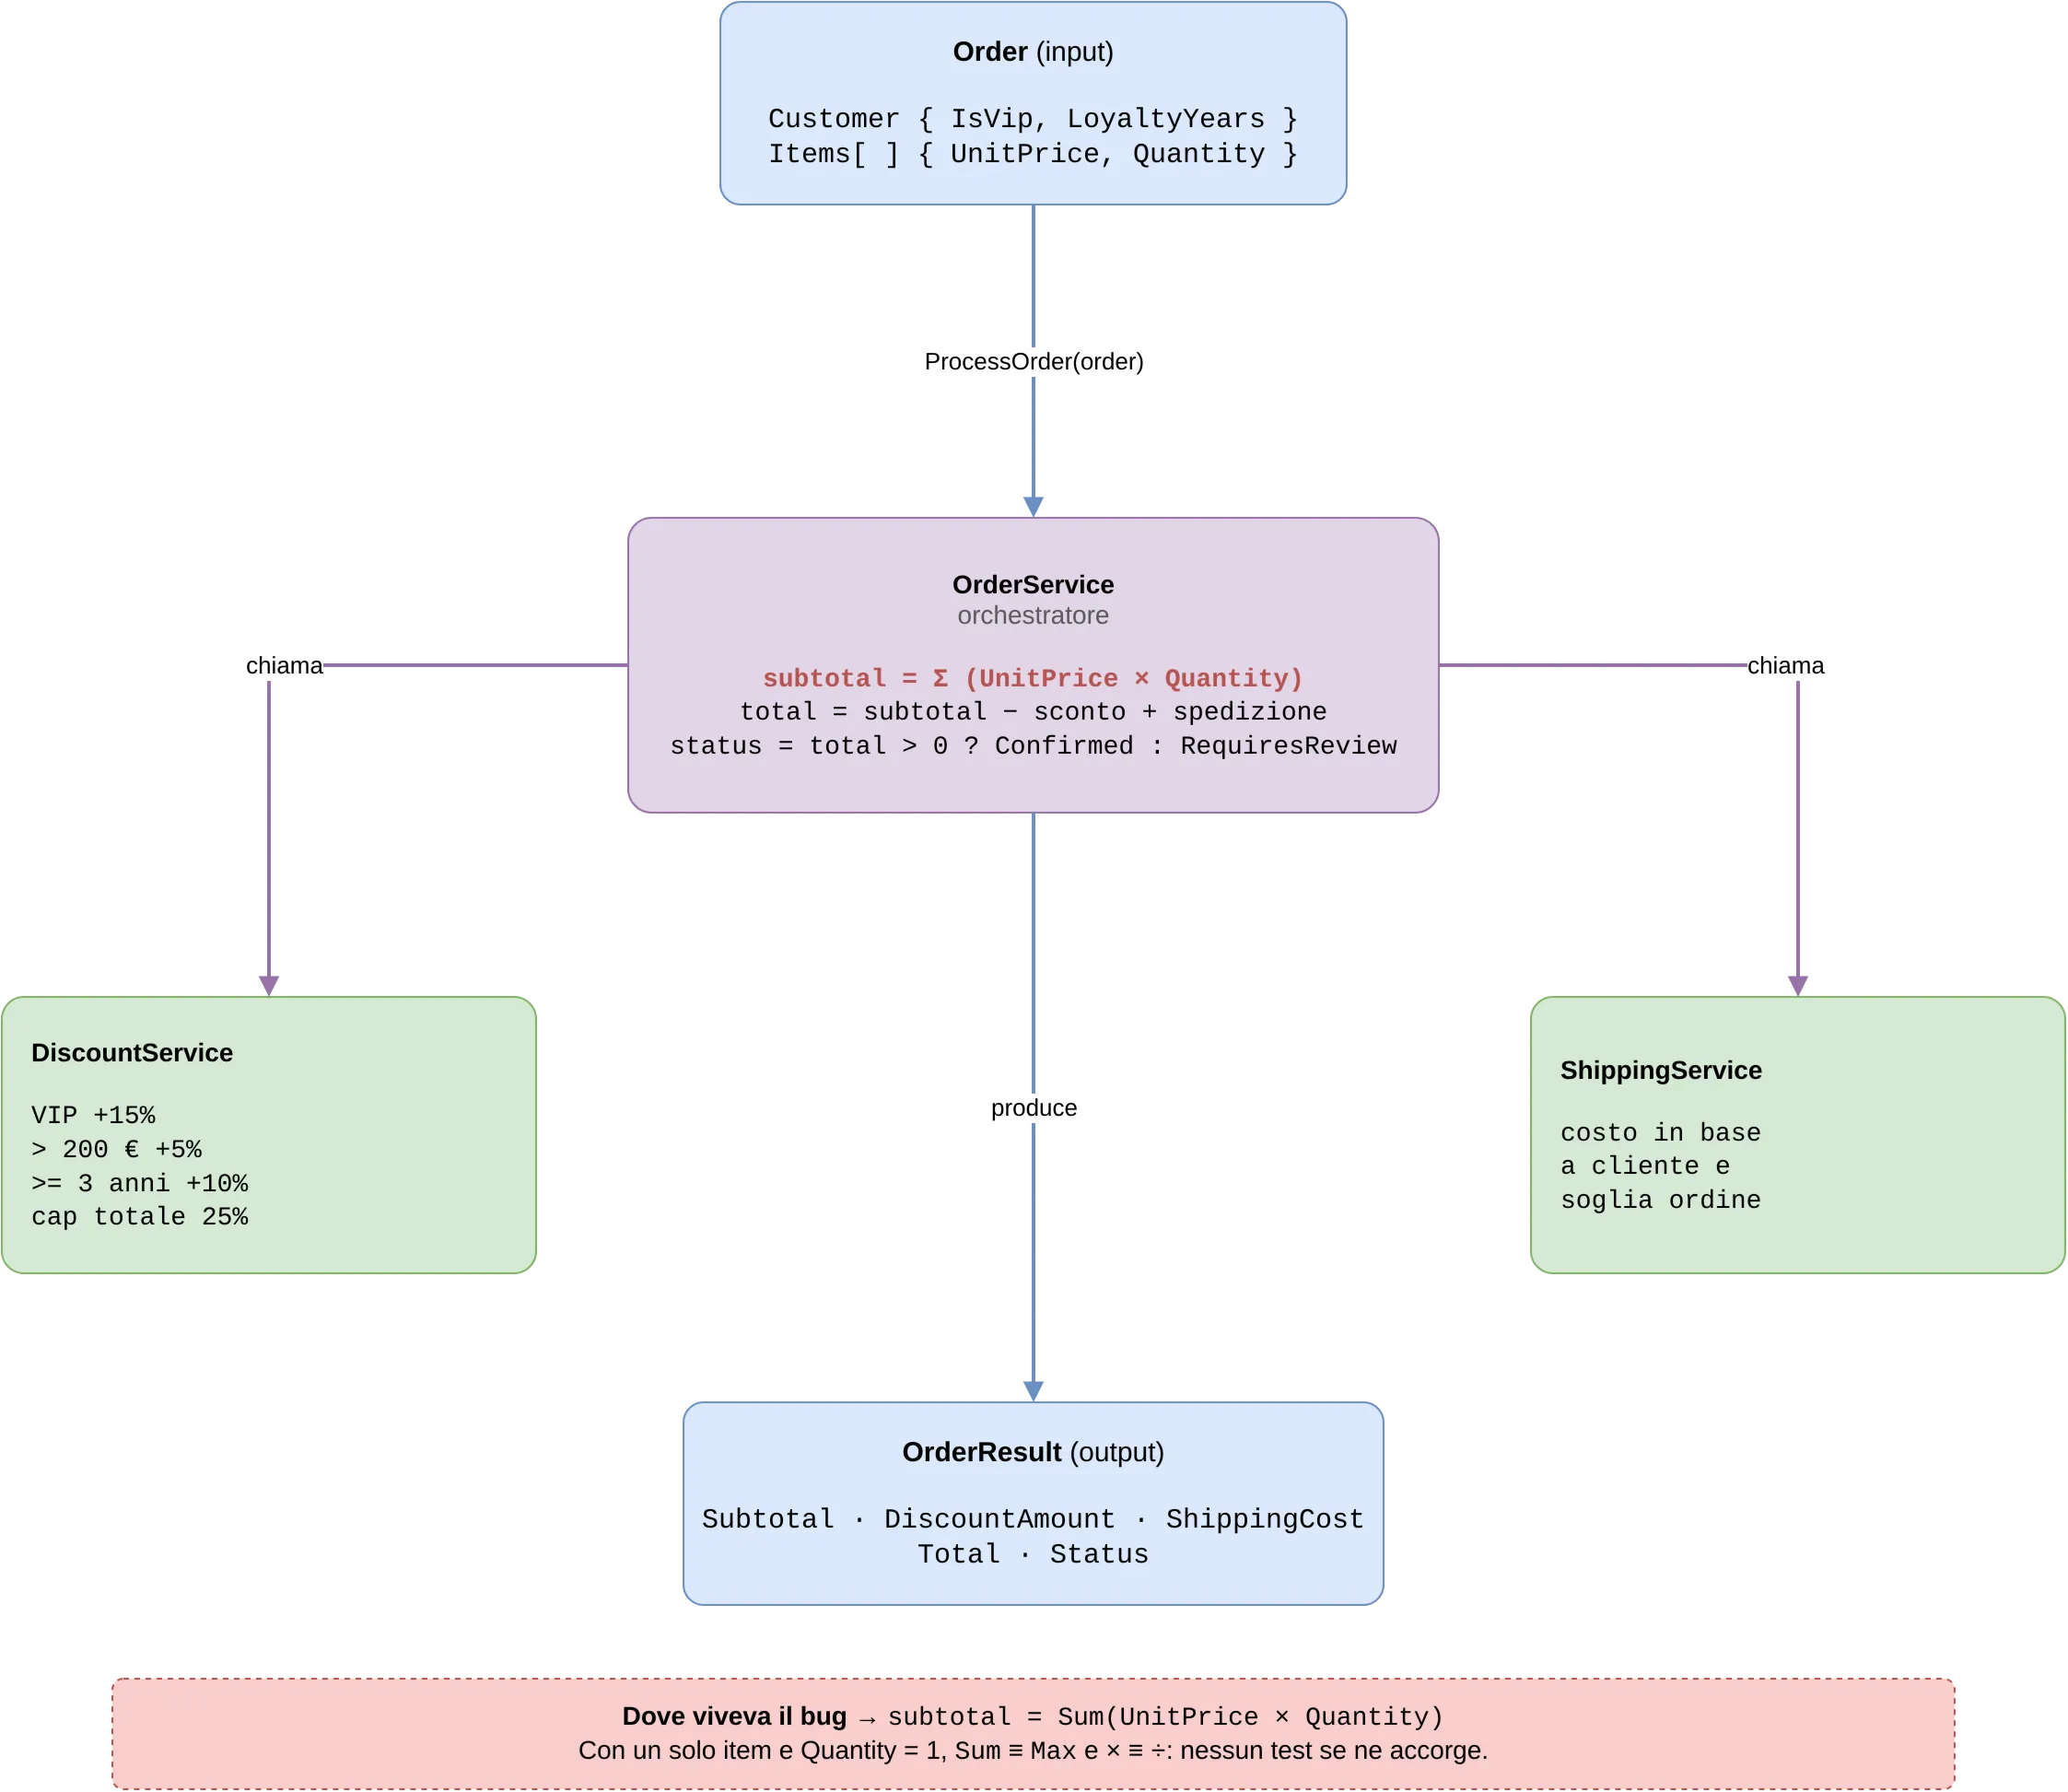
Nothing exotic: three services, one input, one output. Keep an eye on that subtotal: Sum(UnitPrice × Quantity). That is where, weeks later, the bug was hiding.
The code was wrong, the tests stayed green
Coverage answers a precise question: does this code get executed?
It does not answer the question that actually matters: if this code were wrong, would the tests notice?
I understood that by looking at my tests in detail. Three tests, clear names, assertions with exact values. At first glance well made. But all of them with a single item in the order. Quantity always equal to 1.
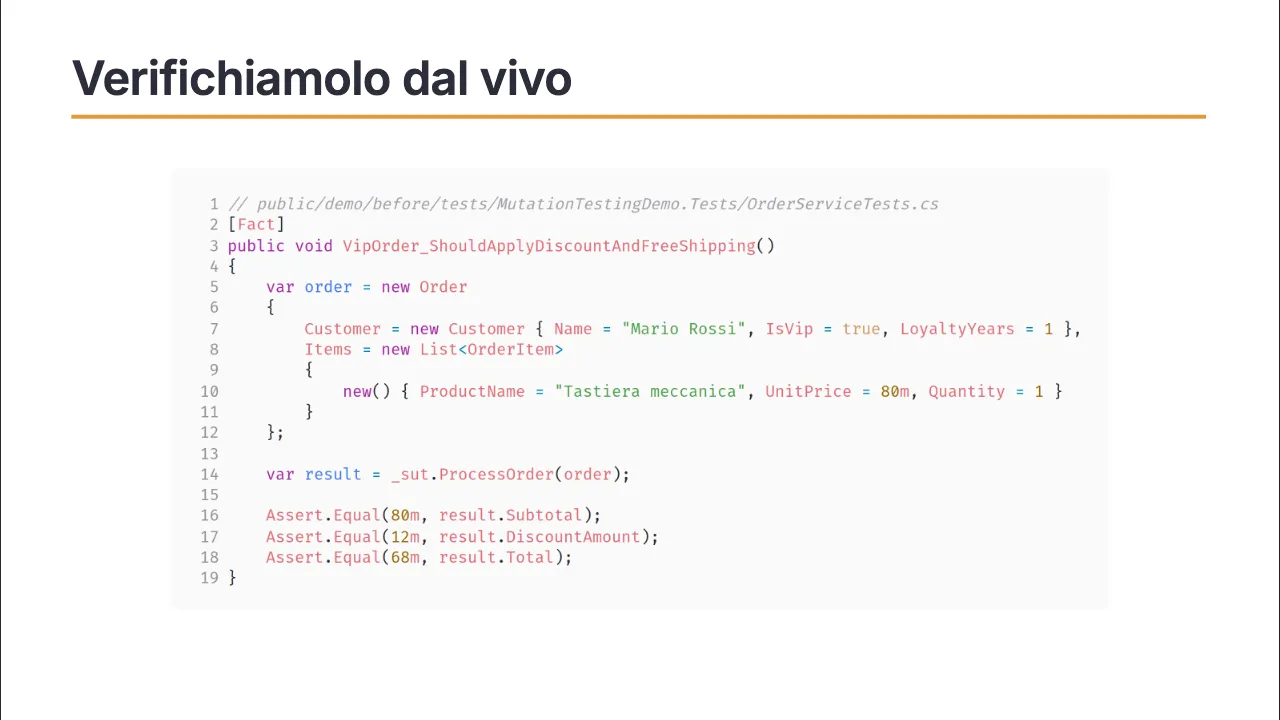
I tried breaking the code on purpose: I changed Sum to Max in the subtotal calculation.
All green. Max of a single element equals the sum of a single element.
I changed the arithmetic operator: × Quantity → ÷ Quantity.
All green. Price × 1 = Price ÷ 1.
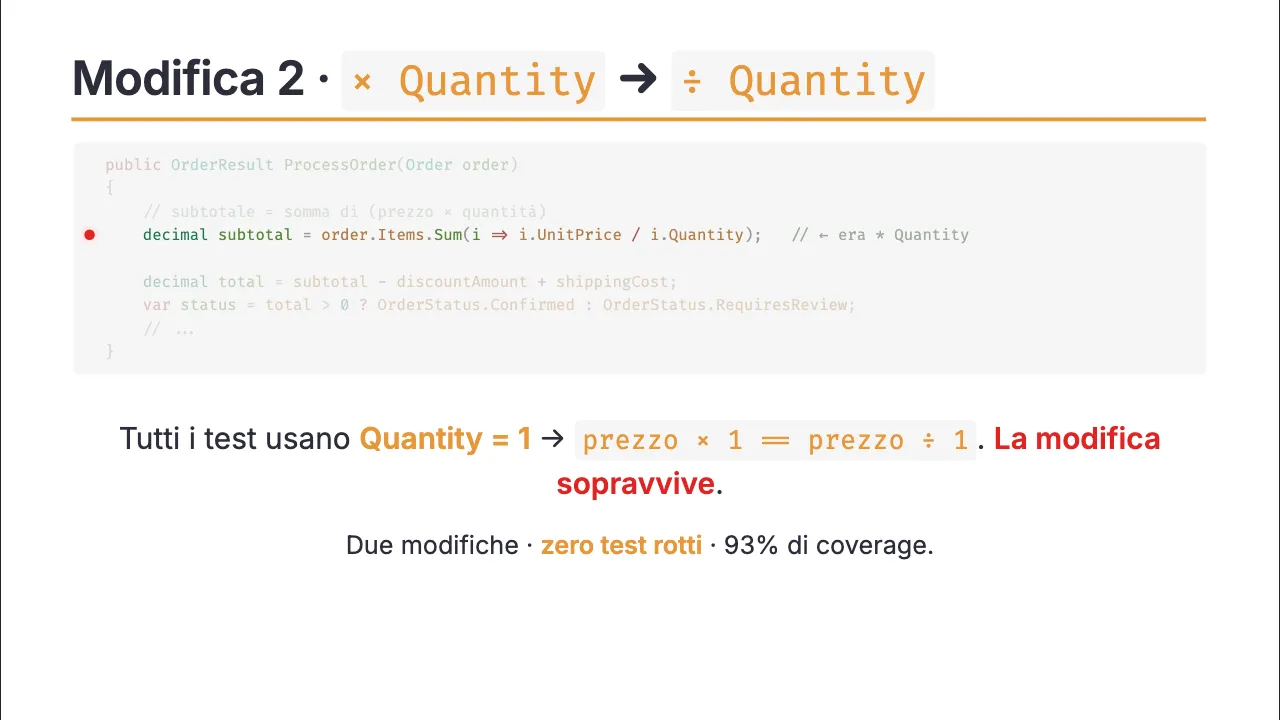
Two changes. Zero broken tests. 93% coverage.
Mutation testing: breaking the code on purpose, systematically
What I did by hand on two lines is called mutation testing. The idea is simple: if a test is reliable, it has to go red when the implementation is wrong. The most direct way to verify that is to introduce controlled changes (mutants) and measure how many of them the tests detect.
One clarification is worth making, because it is the point that confuses people most: the mutant is a change to the application code, not to the tests. The suite stays identical. The tool takes the source, generates hundreds of variants of it, each with a single change (like Sum → Max), and against each one it re-runs the same tests unchanged. If at least one test goes red, the mutant is killed: the tests did their job. If they all stay green, the mutant is survived: there is a hole.
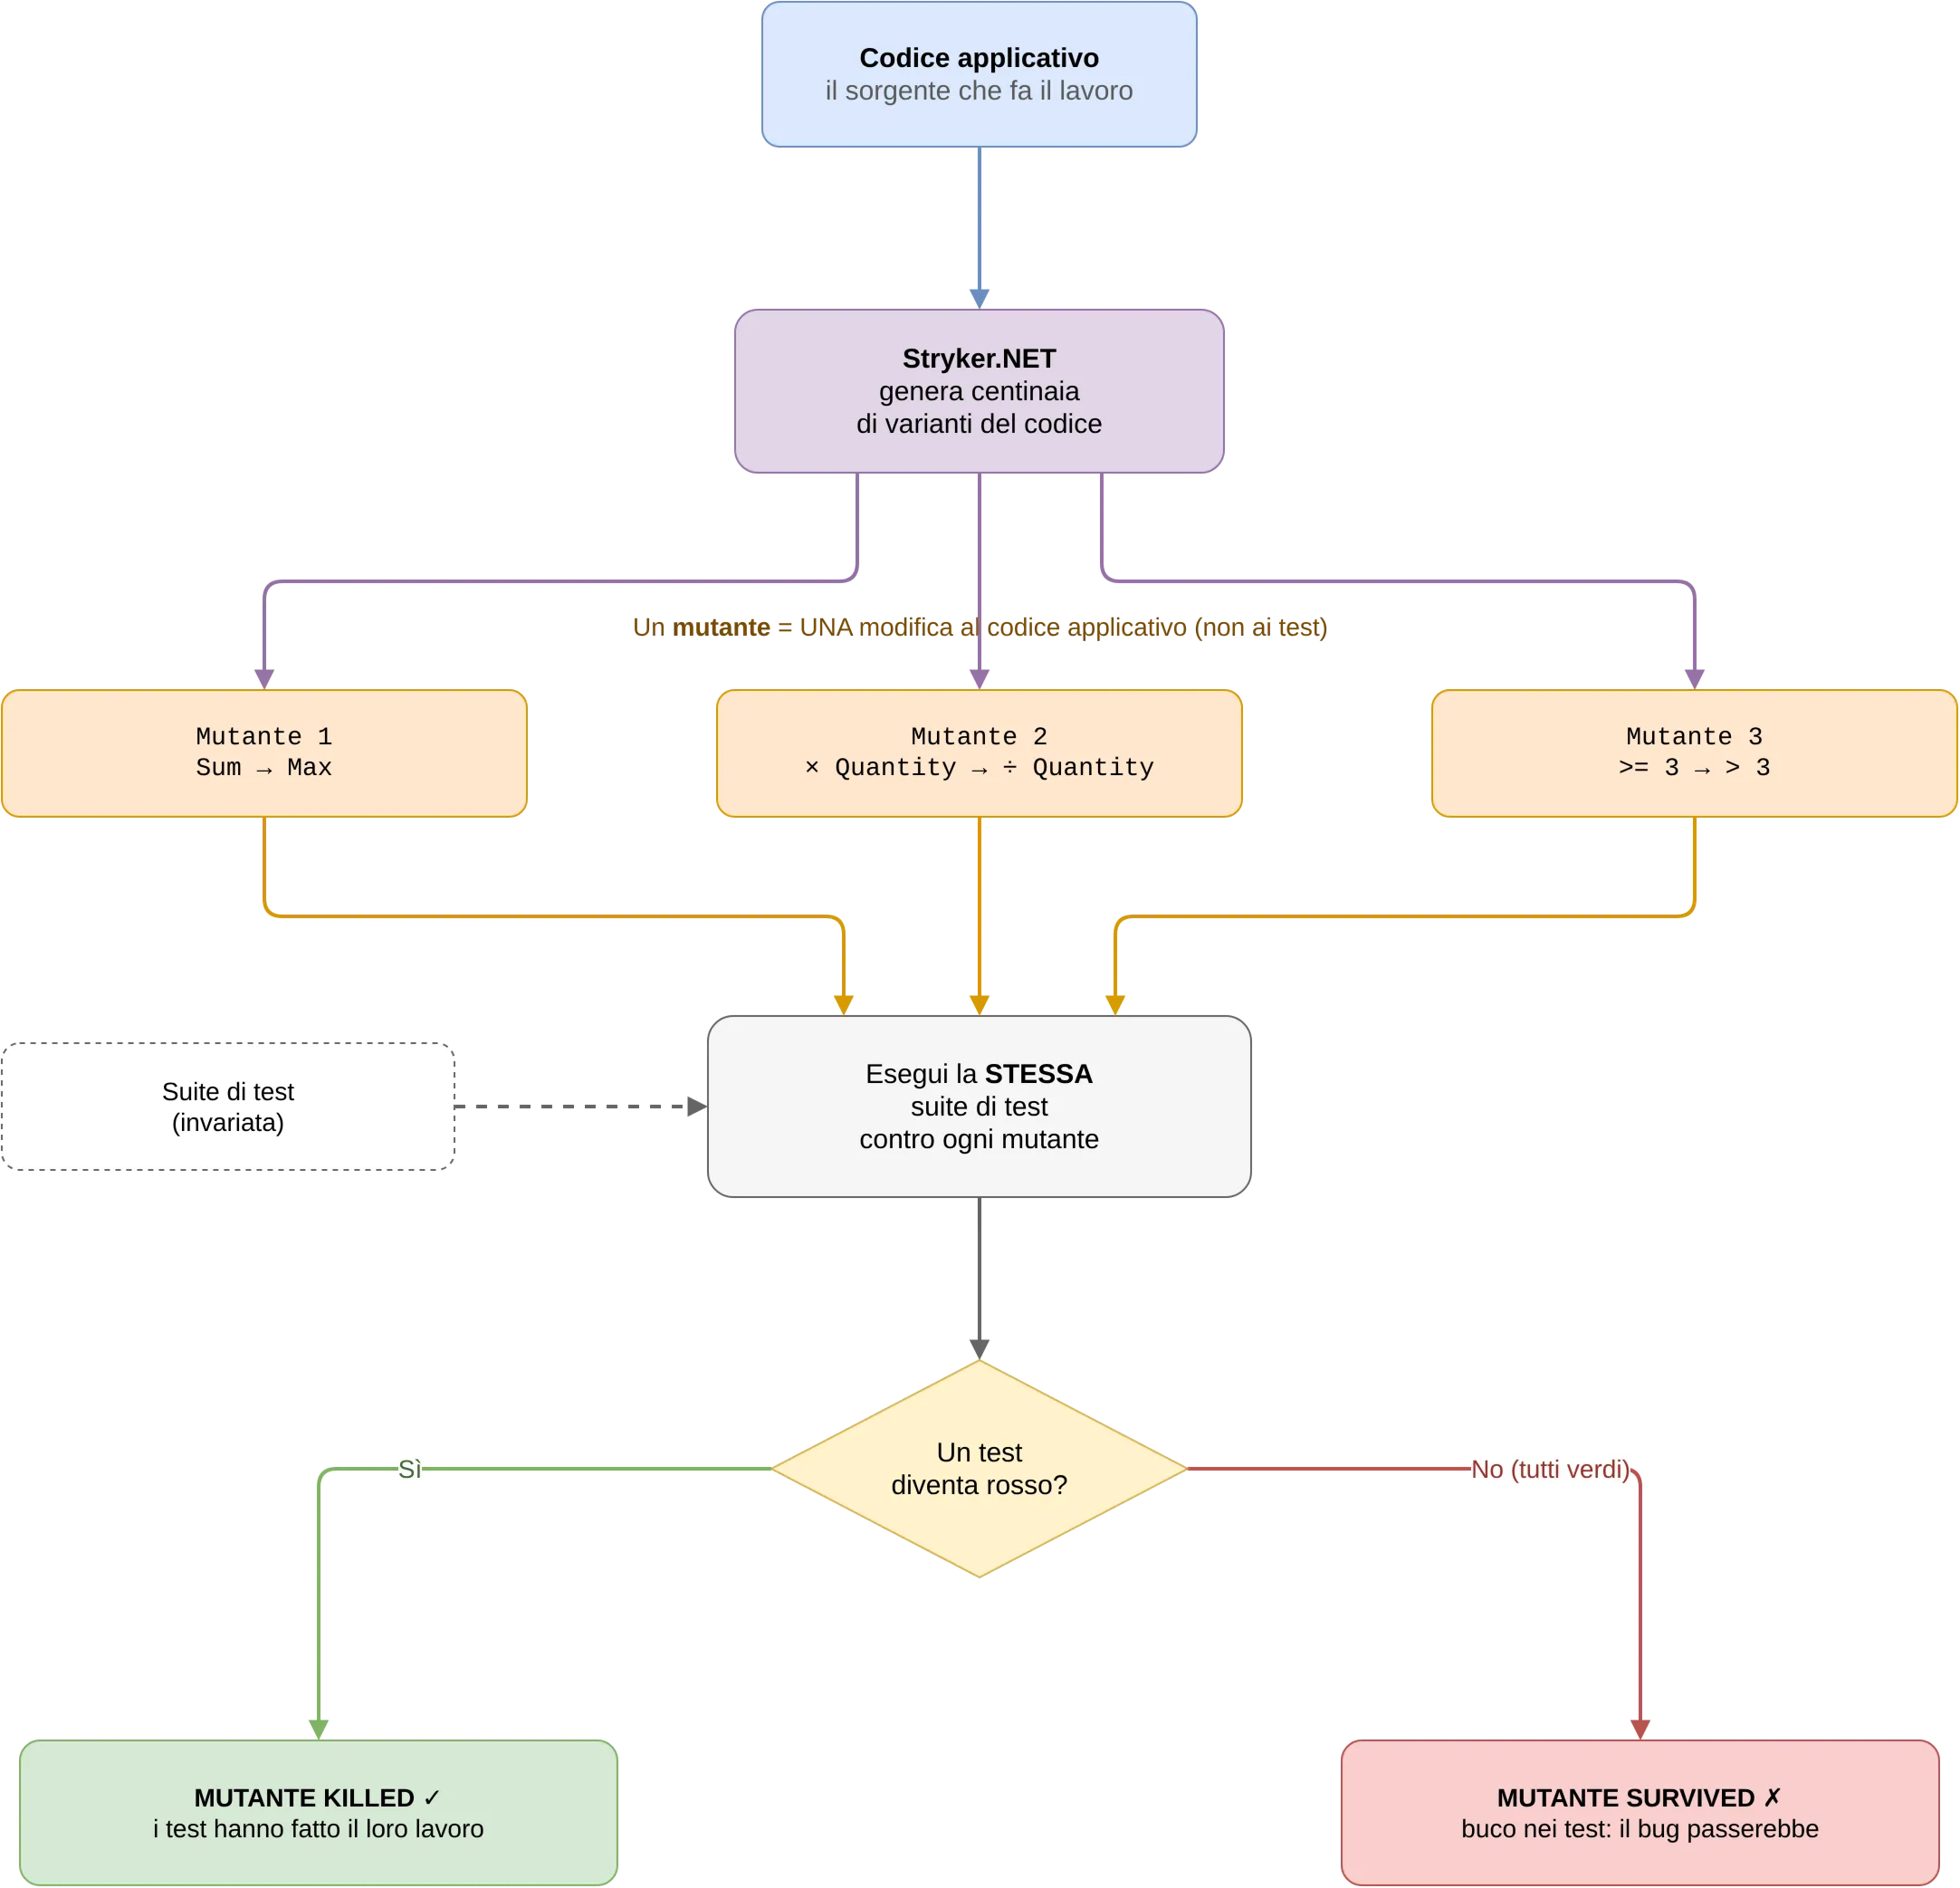
It has existed since the 1970s. Today there are tools that do it automatically across a whole codebase.
On my project I used Stryker.NET. The output is a mutation score (the percentage of mutants the tests manage to kill), but above all an interactive report that takes you straight to the fragile spot.
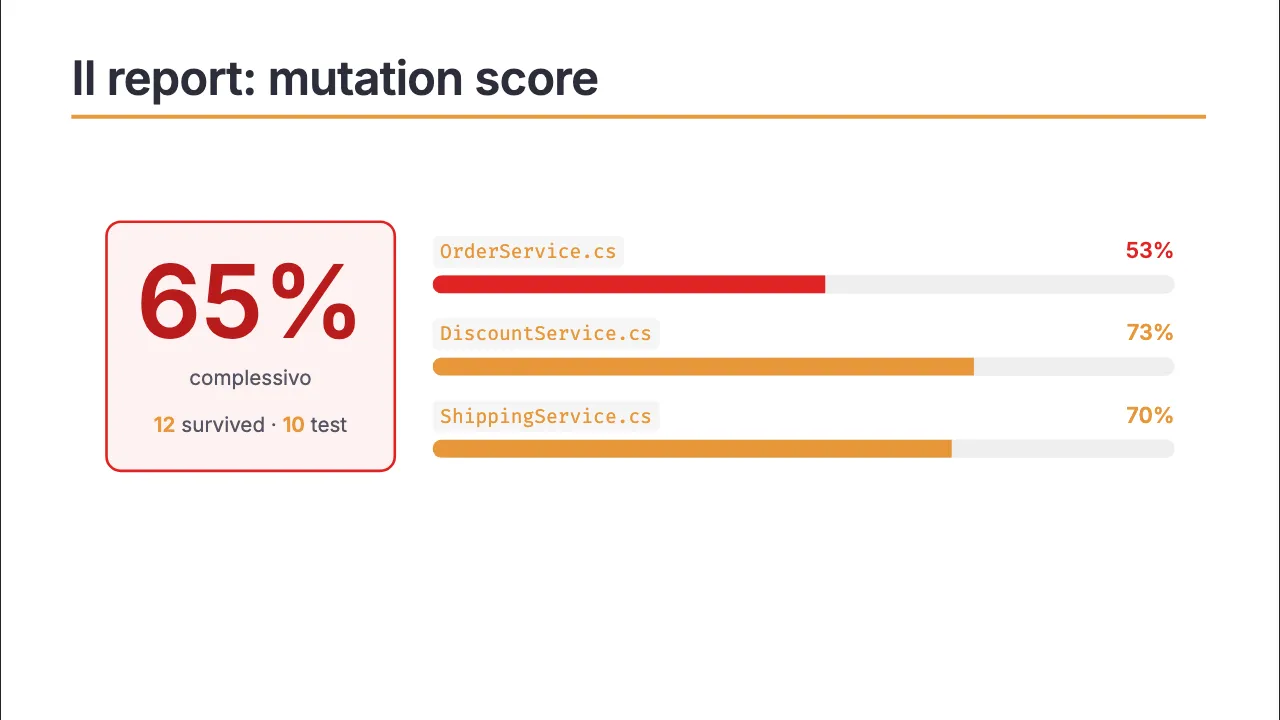
The score was 65%: one mutant in three survived, meaning 35% of the changes to the code made no test fail.
What the report says
Going through the survived mutants I found three families of problem:
1. Non-discriminating data. The test always uses a single item with Quantity=1. Sum and Max give the same result. The bug had been in production for three weeks: it was exactly this mutant.
2. Incomplete assertion. The code calculates OrderStatus (Confirmed or RequiresReview), but no test verifies it. An entire branch of business logic never checked.
3. Uncovered boundary. The loyalty discount kicks in at >= 3 years, but every test uses 5 years. Move the threshold by a year and no test fails.
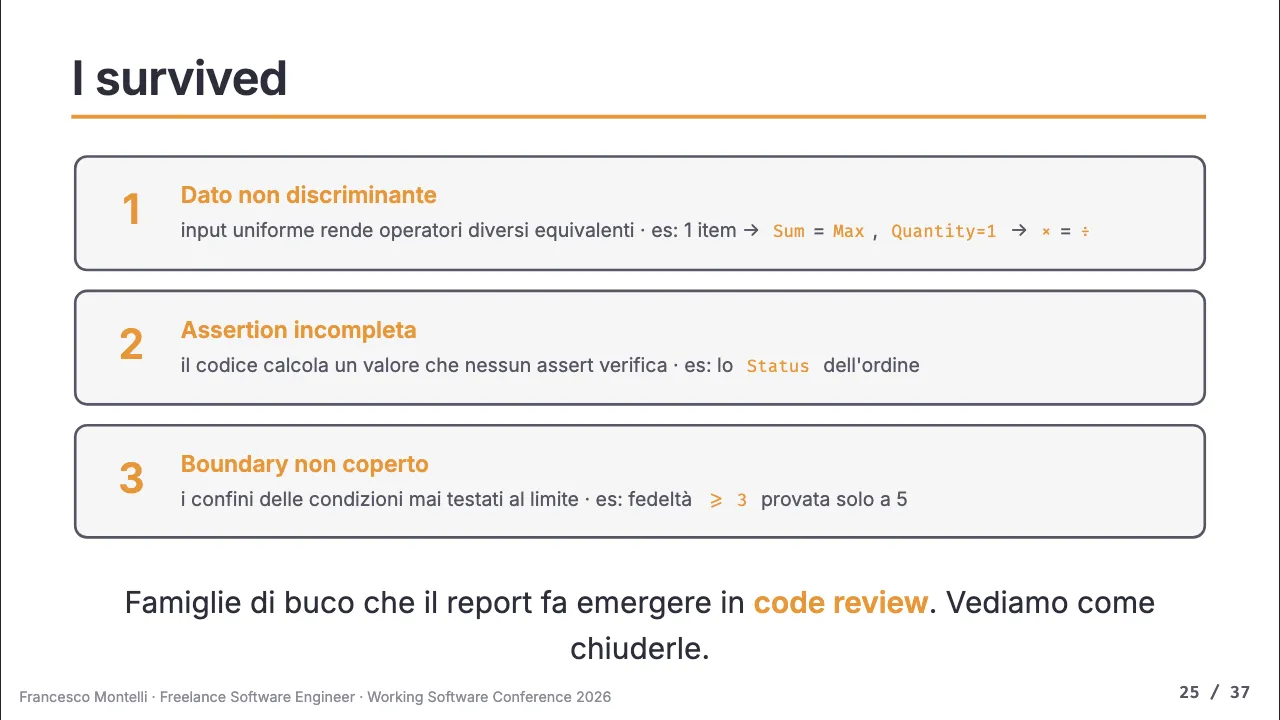
I did not have to guess where to look: the report told me, with the exact diff of every mutant.
The fix
Two targeted changes:
- A test with two items and different quantities: now
SumandMaxgive different results, and so do multiplication and division. - One more line:
Assert.Equal(OrderStatus.Confirmed, result.Status).
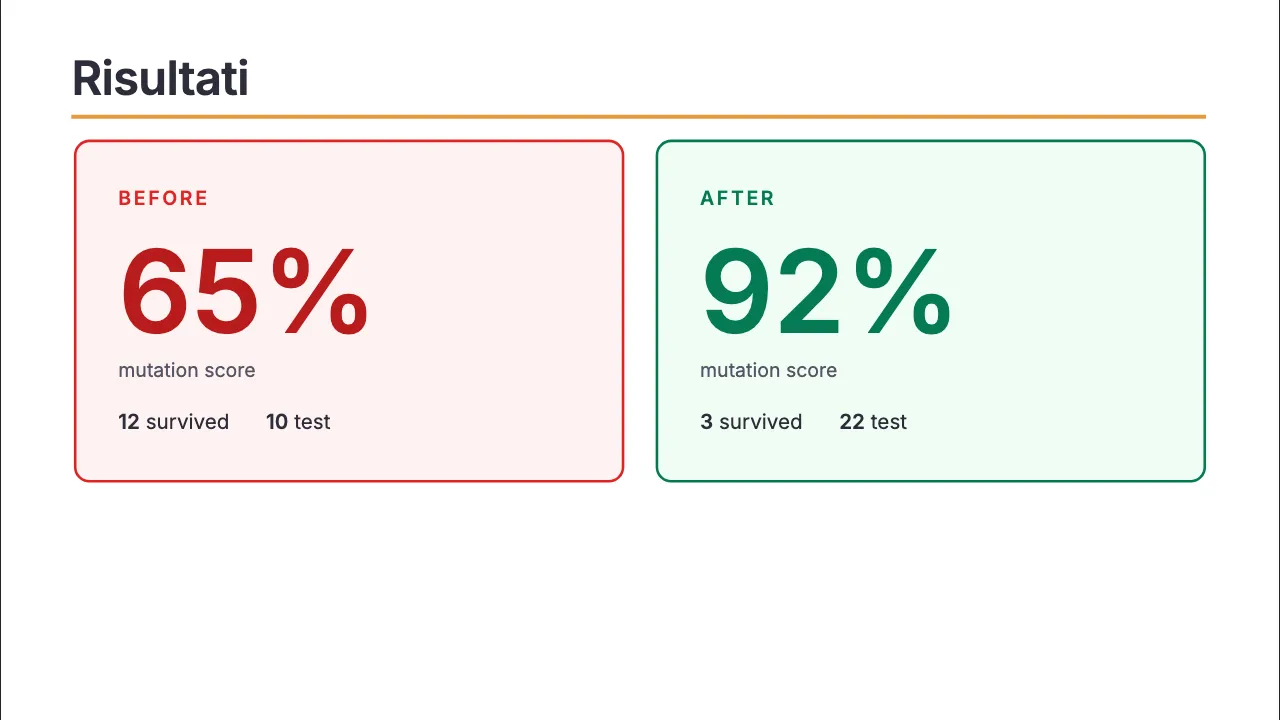
Final score: 92%. From 10 tests to 22. The survived go from 12 to 3 (those 3 are equivalent mutants: they change the syntax but not the observable behaviour, so no test will ever be able to kill them — a known theoretical limit, not a hole in your tests).
The thesis
Coverage tells you whether the code gets executed. The mutation score tells you whether the tests work.
They are two different questions. Both are worth asking.
And this second question holds regardless of who wrote the tests. On my project a good part of them were generated by AI agents, and that was decisive: without them I would not have delivered at that quality in that time. But “who” or “how” they were written tells you nothing about whether those tests are worth anything.
What to do tomorrow
You do not need to adopt it everywhere in a day. Pick one service: the one with the most critical logic, the one the money goes through, the one nobody wants to touch because “it works and nobody knows how”.
Run Stryker (or mutmut for Python, pitest for Java, cargo-mutants for Rust). Read the survived mutants as questions your tests had not yet asked themselves.
With --since:main in CI it mutates only the code changed in the PR: execution time stays proportional to the change, not to the project. With a threshold (break: 60) you block regressions without demanding perfection.
The goal is to build confidence, layer by layer, on concrete evidence. So you can release without being afraid of breaking something. Even on a Friday.
I gave this talk at Working Software Conference 2026: slides, photos and material are here, and the demo code is public on GitHub.
What remains open
What mutation testing does not solve, and what has to be decided by looking at your own code.
- — The mutation score tells you whether the tests notice a change, not whether they verify the right thing: that question is answered only by someone who knows the domain
- — Execution cost grows with the codebase. With `--since:main` it stays proportional to the PR, but a full pass over the whole project is another matter
- — There is no universal threshold: 60 is a starting point for blocking regressions, not a quality target
- — The example is a small order-management flow with logic of its own. On code made mostly of orchestration and framework, the yield of the mutants is lower